Research
Benchmarks, papers, and writing from our team on improving AI agents for real-world healthcare environments.
Writing
Apr 14, 2026
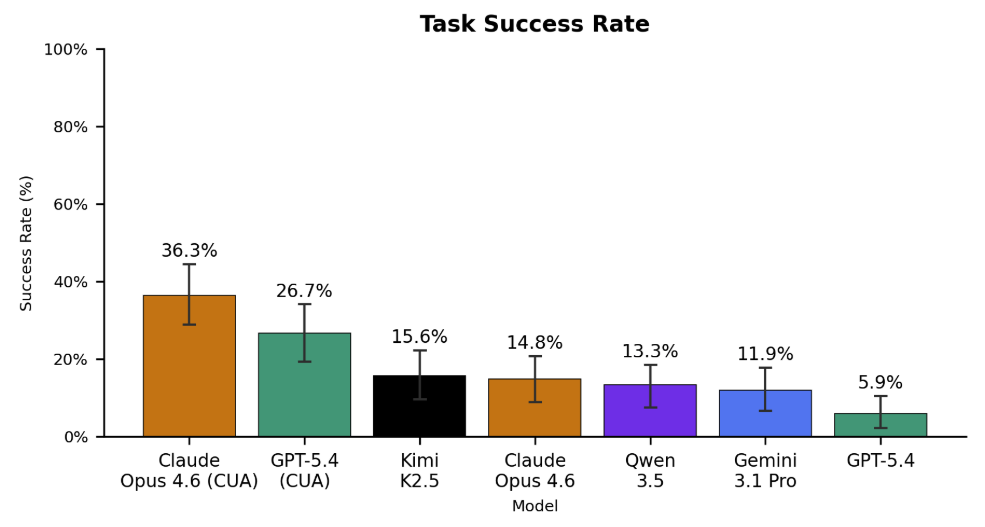
Introducing HealthAdminBench: AI Agents Can Diagnose Rare Diseases, But Can They Handle Your Insurance?
Published at an ICLR 2026 Workshop, HealthAdminBench is the first benchmark for realistically evaluating LLM agents on the healthcare admin workflows that cost our economy $1 trillion/year.
Read more
Apr 13, 2026
Towards the Autonomous Hospital
Our mission is to advance frontier model capabilities for solving real-world, economically meaningful healthcare workflows.
Read morePapers
May 2026Publication
MEDS: An emerging data standard and ecosystem for health AI research
NEJM AI 2026↗
Apr 2026Benchmark
HealthAdminBench: Can AI agents handle your insurance?
ICLR 2026 Workshop→
May 2025Benchmark
MedHELM: Holistic evaluation of large language models for medical tasks
Nature Medicine 2026↗
Apr 2025Publication
Context Clues: Evaluating long-context models on EHR data
ICLR 2025↗
Mar 2025Benchmark
Top of the CLASS: Benchmarking LLM agents on real-world enterprise tasks
ICLR 2025 Workshop↗
Jan 2025Publication
Zero-shot clinical trial patient matching with large language models
NEJM AI 2025↗
May 2024Publication
Automating the enterprise with foundation models
VLDB 2024↗
Feb 2024Benchmark
MedAlign: A clinician-generated dataset for instruction following with EHRs
AAAI 2024↗
Dec 2023Benchmark
EHRSHOT: An EHR benchmark for few-shot evaluation of foundation models
NeurIPS 2023↗
Nov 2023Benchmark
INSPECT: A multimodal dataset for patient outcome prediction
NeurIPS 2023↗
Oct 2023Publication
The shaky foundations of large language models for electronic health records
npj Digital Medicine 2023↗